
 Français
 English
 Deutsch
 Español
 Italiano
 Português do Brasil
 Tiếng Việt
 ไทย
 Bahasa Indonesia
 Русский
 العربية
 हिन्दी
 GM / 42NOTE DE TERRAIN // 2026
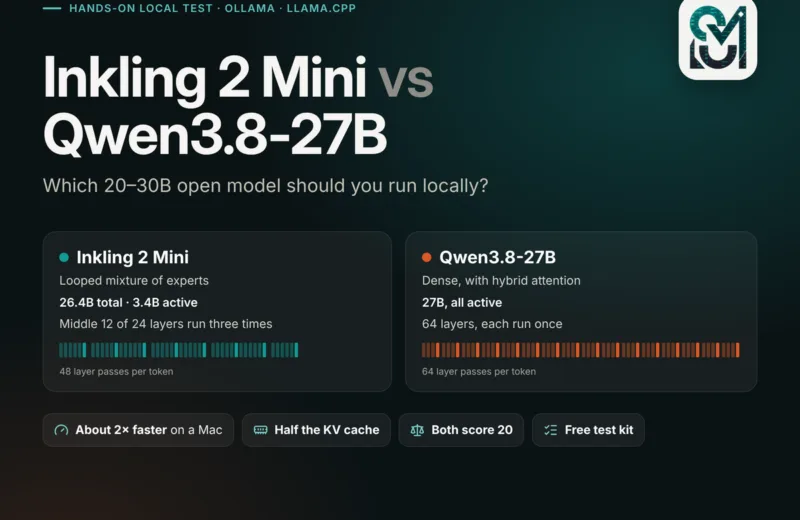
Inkling 2 Mini vs Qwen3.8-27B: Which 20–30B Open Model Should You Run Locally?
Inkling 2 Mini local test vs Qwen3.8-27B: tokens per second, memory, coding and agent tasks on Ollama and llama.cpp, and whether looping is worth it.